Decision Models Cut Wasteful LLM Calls in Agent Stacks
Decision model
A model that returns a bounded label, score or probability rather than open-ended generated text.
Noul
Jev’s yes/no primitive; it returns a probability that a statement is true.
Accepted-case error
The error rate among cases a system allows to proceed automatically after applying confidence thresholds.
Calibration
The degree to which model probabilities match real-world correctness rates on the target workload.
VentureBeat
news
Companies are paying LLMs to generate text for decisions that only need a label. Jev offers a cheaper way
Amplitude
other
An analysis of Jev: Faster and cheaper, but watch the accuracy
Red Hat Developer
other
Run decision models on vLLM and Red Hat AI using DiffusionGemma
Bounded decisions
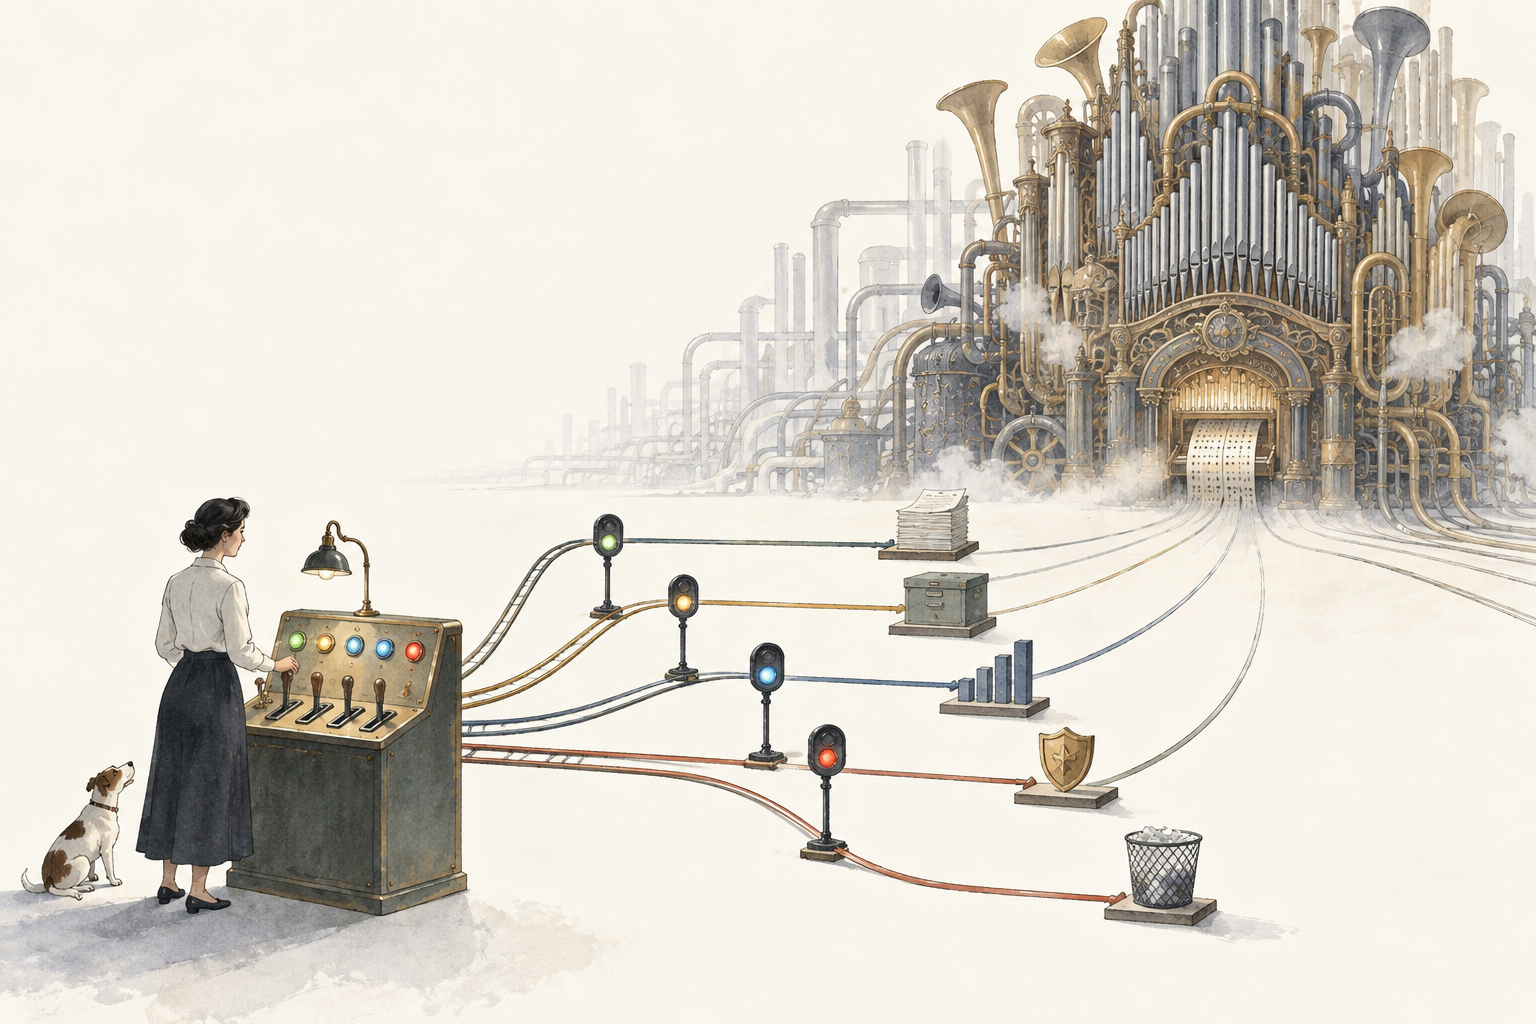
Jev-style models return choices, scores and yes/no probabilities instead of generated text for routing, triage, approval and scoring tasks.
Verified price
Multiple sources list TypeSafe Jev 1.13 at $0.042 per 1 million input tokens with free output.
Measure accuracy
Typed outputs remove parsing failures, but teams still need calibration, thresholds and accepted-case error measurements.
AI application teams can cut latency, cost and failure modes by moving many branch-point calls away from text-generating LLMs and into calibrated decision layers. TypeSafe AI’s Jev makes a straightforward claim: when software needs only a label, score or yes/no probability, asking a language model to generate prose or JSON and then parsing it back into a typed value is often unnecessary work.1
This pattern does not replace LLMs. It divides labor. Generative models still handle drafting, summarization, code, open-ended reasoning and conversation. Decision models handle bounded choices: route this ticket, approve this tool call, score this lead, flag this message, choose this fallback or decide whether to escalate to a human.3
Jev is the highest-profile example. It exposes three primitives: Choice, for selecting from a fixed set; Score, for placing an input on an ordered scale; and Noul, for returning a probability for a yes/no statement.3 Instead of asking for JSON, the application supplies state and declared answer spaces. Jev returns typed answers and probabilities that normal code can threshold, audit and route.5
Modern agent stacks are full of small decisions. A support agent may classify intent before drafting a reply. A RAG pipeline may score whether a passage is relevant before sending it to a bigger model. A tool-using agent may decide whether a proposed action is safe, whether confidence is high enough or whether a user request belongs in a specialist workflow.
Many of those calls do not require language generation. A general LLM used as a classifier still pays for decoding, structured-output constraints, parsing, retries and format validation. A decision layer can return the value the application needs directly, often with a probability distribution rather than a paragraph.1
That is the efficiency argument. The reliability argument is more subtle. Typed output eliminates malformed JSON and out-of-schema labels, but it does not guarantee the semantic judgment is correct. If the choices are billing, technical and sales, a model cannot invent legal; it can still choose billing when the true answer is technical.5
For engineers, the useful pattern is not “trust the decision model.” It is “measure the decision model, accept only the confident region, and route the uncertain tail elsewhere.” Amplitude’s practitioner analysis makes that point directly: faster, cheaper decisions still require evaluation, calibration, thresholds and measurement against ground truth.2
As of the September 28 coverage, Jev was in early access and positioned for text-only decision tasks. VentureBeat reported typical latency in the 70 ms to 500 ms range and pricing of $0.042 per million input tokens, with output tokens free.1 Composio’s developer guide likewise listed the stable model as jev-1.13.0, priced at $0.042 per million input tokens with free output, and described a 64k total request limit and text-only input.5
ProviderBench’s September 29 catalog independently listed TypeSafe: Jev 1.13 at $0.042 per 1 million input tokens, free output and a 32K context figure.10 That creates a practical implementation note: teams should verify the effective request and context limits in the SDK or provider they use, because third-party catalogs and integration guides may describe different limit fields.
Flavio Copes’ Node.js walkthrough also verifies the SDK workflow: developers can call systemOne, use jev-latest, observe versioned responses such as jev-1.13.0, and bill on input tokens rather than generated output.4 His tutorial highlights an engineering advantage for TypeScript-heavy stacks: labels flow into typed branches, making exhaustive switches and compile-time checks possible around probabilistic model decisions.4
Access is not limited to TypeSafe’s direct API. Emergent announced Jev access through its Universal Key, so builders can use Jev inside Emergent projects without a separate TypeSafe account or key.8 VentureBeat also reported that TypeSafe paused its signup queue while some developers used the model through alternate routes such as OpenRouter.1
The core claim is about latency and control flow, not a magic model. A decision model is useful when four conditions are true:
Pulumi’s GeoDeploy example shows this split in a real infrastructure workflow. TypeScript computes prices, filters candidates and enforces constraints; Jev selects among already-valid cloud regions and scores bounded criteria; Pulumi provisions the selected resources.6 Jev does not do arithmetic, generate code or invent cloud regions. The application supplies the region IDs and retains the final control flow.6
That separation is the main safety property. A decision model can make a semantic judgment over messy state, while deterministic software enforces hard constraints, permissions, budgets and side-effect rules.
The clearest use cases are high-volume, bounded and auditable:
Composio’s examples include support routing, document candidate selection, warehouse classification, agent harness decisions, browser navigation and live-chat moderation.5 Emergent describes the same split for app builders: use LLMs for generation and Jev for the repeatable decisions between those steps.8
QuanticData’s lead-scoring test grounds the idea in a bounded business task. On 183 hand-labeled businesses, Jev with one Noul instruction classified 175 correctly, while hand-tuned keyword rules classified 176 correctly.9 The more important result was thresholding: accepting above 0.8, dropping below 0.3 and reviewing the middle decided 164 of 183 leads automatically with no errors in that sample, leaving 19 for human review.9
That is the decision-model value proposition in miniature: not necessarily beating rules everywhere, but reducing rule-writing effort while producing confidence bands that let teams trade coverage for error.
The failure mode is easy to miss because the output looks clean. A valid enum is not the same as a correct decision. Amplitude’s analysis warns that decision models can share the same accuracy pitfalls as LLMs, only faster and cheaper.2
Teams need evaluation sets for each decision point. A ticket router should be tested on labeled tickets. A tool-call gate should be tested on accepted and rejected historical actions. A lead scorer should be tested against real conversions or human labels. Thresholds should be selected on held-out data, not tuned until a demo looks good.
The right metric is often not raw accuracy alone. For production routing, engineers should track:
Trilogy AI frames the same comparison around coverage versus accepted-case error across Jev and open alternatives.7 That framing is useful because decision layers are usually deployed as selective classifiers: they act only when confidence is high enough and fall back otherwise.
Jev is not the only way to build this layer. VentureBeat described a burst of open alternatives, including SemIf and Laya, that use stronger pretrained models to make bounded decisions without conventional token-by-token JSON generation.1
SemIf takes a lightweight route: it reads option probabilities from a frozen Qwen-family model rather than training a new model, according to VentureBeat’s summary.1 That makes it attractive as an experiment or baseline, but teams still need to validate latency, label coverage and calibration on their own workloads.
Laya takes a more model-specific route. VentureBeat reported that it builds a decision model on a ModernBERT-large backbone and answers in roughly tens of milliseconds per question on an Nvidia T4, while also noting that its base checkpoints needed fine-tuning to perform well on typed-decision benchmarks.1 In practice, that makes Laya closer to a deployable classifier stack: potentially fast and open, but dependent on training, calibration and maintenance.
Red Hat’s DiffusionGemma path is another open route. Red Hat describes a vLLM structured-read approach in which a diffusion model fills predefined answer slots and exposes probabilities, allowing a Jev-like /v1/systemone example endpoint on infrastructure the enterprise controls.3 That matters for regulated, air-gapped or sovereign deployments that cannot send routing and approval decisions to a hosted third-party API.3
The trade-off is operational. Hosted Jev offers a productized API and pricing. Open routes reduce vendor dependency but shift responsibility for serving, GPU capacity, calibration, endpoint semantics, monitoring and model updates to the application team.
Engineers should start with an audit of LLM traffic. Separate calls that produce language from calls that only produce decisions. The second group is the candidate set: routing, triage, approval, scoring, guardrails and cheap evaluation.
For each candidate, define the answer space explicitly. Include an other, unknown or human_review option where appropriate; otherwise, a model forced to choose among bad labels will choose the nearest bad label.4
Then build a harness before replacing production calls. Collect labeled examples, run the existing LLM path, run the decision layer, and compare not just accuracy but cost, latency, confidence calibration and downstream business impact. Add thresholds that decide when to accept, when to escalate to a bigger model and when to send to a human.
Finally, keep deterministic code in charge. Use decision models for semantic judgments; use code for arithmetic, permissions, policy invariants, idempotency, schema validation and side effects. Pulumi’s infrastructure example is a useful reference architecture because it lets Jev choose only among candidates the application has already priced and validated.6
The return of classifier-style models is not nostalgia for pre-ChatGPT machine learning. It is an engineering response to agent complexity. As applications add more agents, tools, policies and model tiers, they create more branch points. Many of those branch points need a calibrated decision, not generated text.
Jev’s early-access pricing and latency make the pattern visible, and open projects such as SemIf, Laya and DiffusionGemma structured reads show that the idea is broader than one vendor.137 The winning implementations will not be the ones with the cleanest typed output alone. They will be the ones that prove low accepted-case error at useful coverage, under real application load.


Comments